Checked November 6, 2026 · Label: Local, with one cloud-only model flagged
Short answer: the most useful local AI news this week is MiMo V2.6 arriving in Ollama, because anyone with 16GB can try it with one command. The loudest is Ripple-65B, a new US coding model for 48GB to 64GB machines. The biggest, Kimi K3.1 Pro, won't fit at home at all.
What should you try first?
| Release | What it is | Memory | Try it? |
|---|---|---|---|
| MiMo V2.6 9B | Xiaomi's coding model, now in Ollama | 16GB | Yes, one command |
| Xing4.0 29B | China Telecom model, now in llama.cpp | 24GB to 32GB | If you use the command line |
| Ripple-65B Preview | New US coding model | 48GB to 64GB | If you already own the hardware |
| Kimi K3.1 Pro | 2.8T model from Moonshot AI | 1,561GB of weights | Not locally |
Ollama 0.40.15 adds MiMo V2.6 and decision models
Ollama v0.40.15 adds Xiaomi's mimo-v2.6 and AutoTrust decision models, which read text and return choices, yes or no probabilities, or ratings. The notes say autotrust-jev is supported on Apple silicon in this release. Recurrent and vision GGUF models can now serve more than one request at a time, and running ollama with no arguments opens a welcome launcher.
LM Studio Bionic 1.2.0 ships the oMLX engine
Bionic 1.2.0, dated November 5, includes oMLX 0.1.0, an engine for Apple Silicon Macs, along with llama.cpp 2.67.0 extension packs. It also fixes chat template parsing for Flint models and fixes Mac updates reopening the current version. New to the app? Our LM Studio beginner's guide starts from zero.
llama.cpp adds Ripple and Xing4.0
Two model families joined llama.cpp on November 5: Ripple and Xing4.0. llama.cpp support usually comes before app support, so these are the ones to watch in Ollama and LM Studio. Neither was listed in Ollama when we checked on November 6, 2026. Ripple Preview was added later, in Ollama v0.40.16 on November 9; see the update on how to run Ripple-65B locally.
How do this week's models compare?
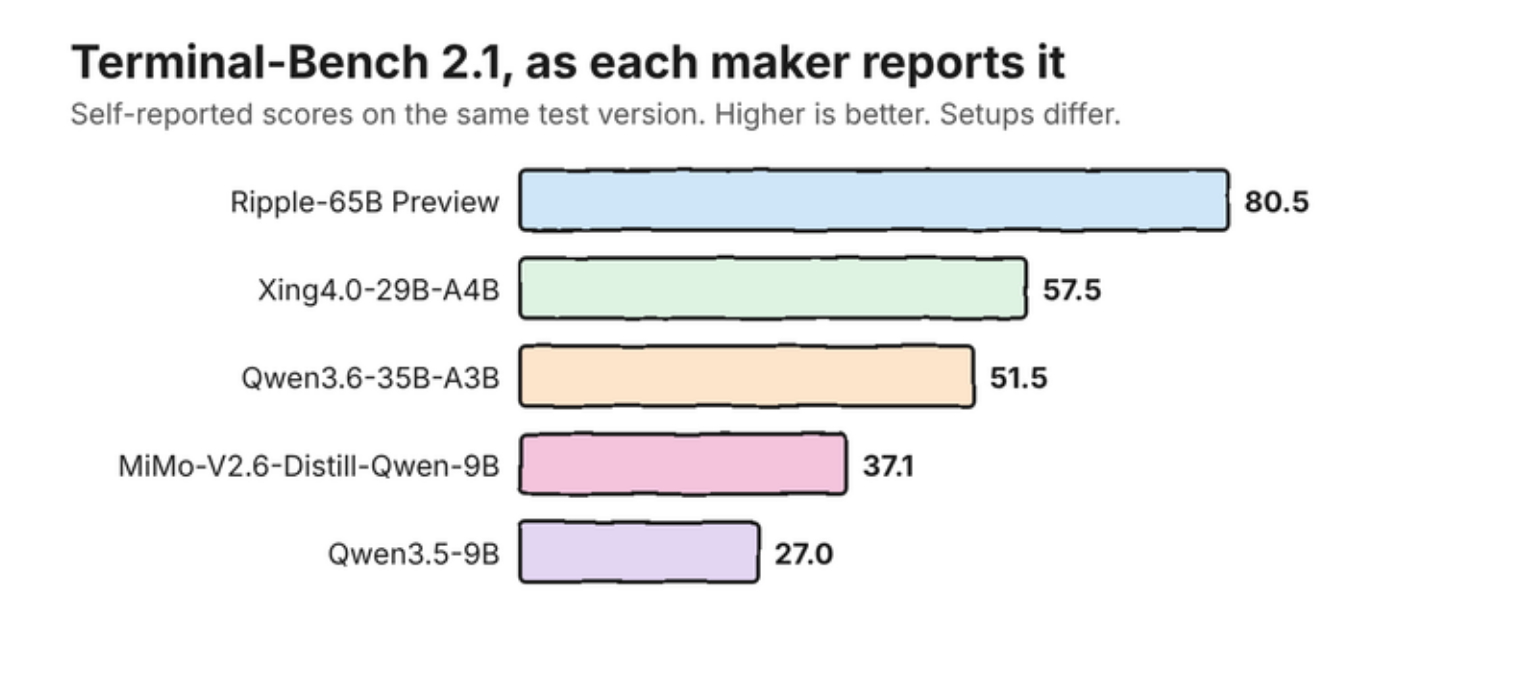
Bigger models score higher, and this chart shows the cost of going small. Treat it as a rough guide: each maker ran its own test, with its own setup.
Two smaller models to watch
Microsoft Mage-VL-Cowork is a 4B Apache 2.0 vision model trained to use a computer, mixing screen clicks with terminal commands. Its card reports 66.0% on OSWorld-Verified. SenseNova-Loop-9B-Preview, released October 30, is an Apache 2.0 multimodal model for long-context agent work. Neither has an Ollama listing that we could find, so both are for tinkerers for now.
Common questions about this week's local AI news
What is the newest model I can run in Ollama?
This week's additions include mimo-v2.6, a 9B coding model from Xiaomi that needs Ollama 0.40.15 or newer. Check the Ollama library for anything added since November 6, 2026.
Which new local AI model should a beginner try?
MiMo V2.6 9B, if you have 16GB of memory. It takes one command and is a 6.6GB to 8.7GB download.
What is oMLX in LM Studio?
LM Studio's changelog lists oMLX as an engine for Apple Silicon Macs, included in Bionic 1.2.0 as version 0.1.0.
How we researched this: a roundup from release notes and model cards, not a hands-on test. Illustrations are original artwork and do not depict a tested product. Older news lives on our news page.
Sources
- Ollama release notes - Releasebot
- Bionic changelog - LM Studio
- Ripple, pull request 31692 - llama.cpp, GitHub
- Xing4.0, pull request 31589 - llama.cpp, GitHub
- microsoft/Mage-VL-Cowork - Hugging Face
- sensenova/SenseNova-Loop-9B-Preview - Hugging Face